Operational Knowledge Repository
Most company knowledge is trapped in local download folders, scattered cloud drives, and forgotten draft notes. We set up a clean, local-first filing system that keeps rough ideas separate from active company policy—so your team and your AI tools get reliable answers.
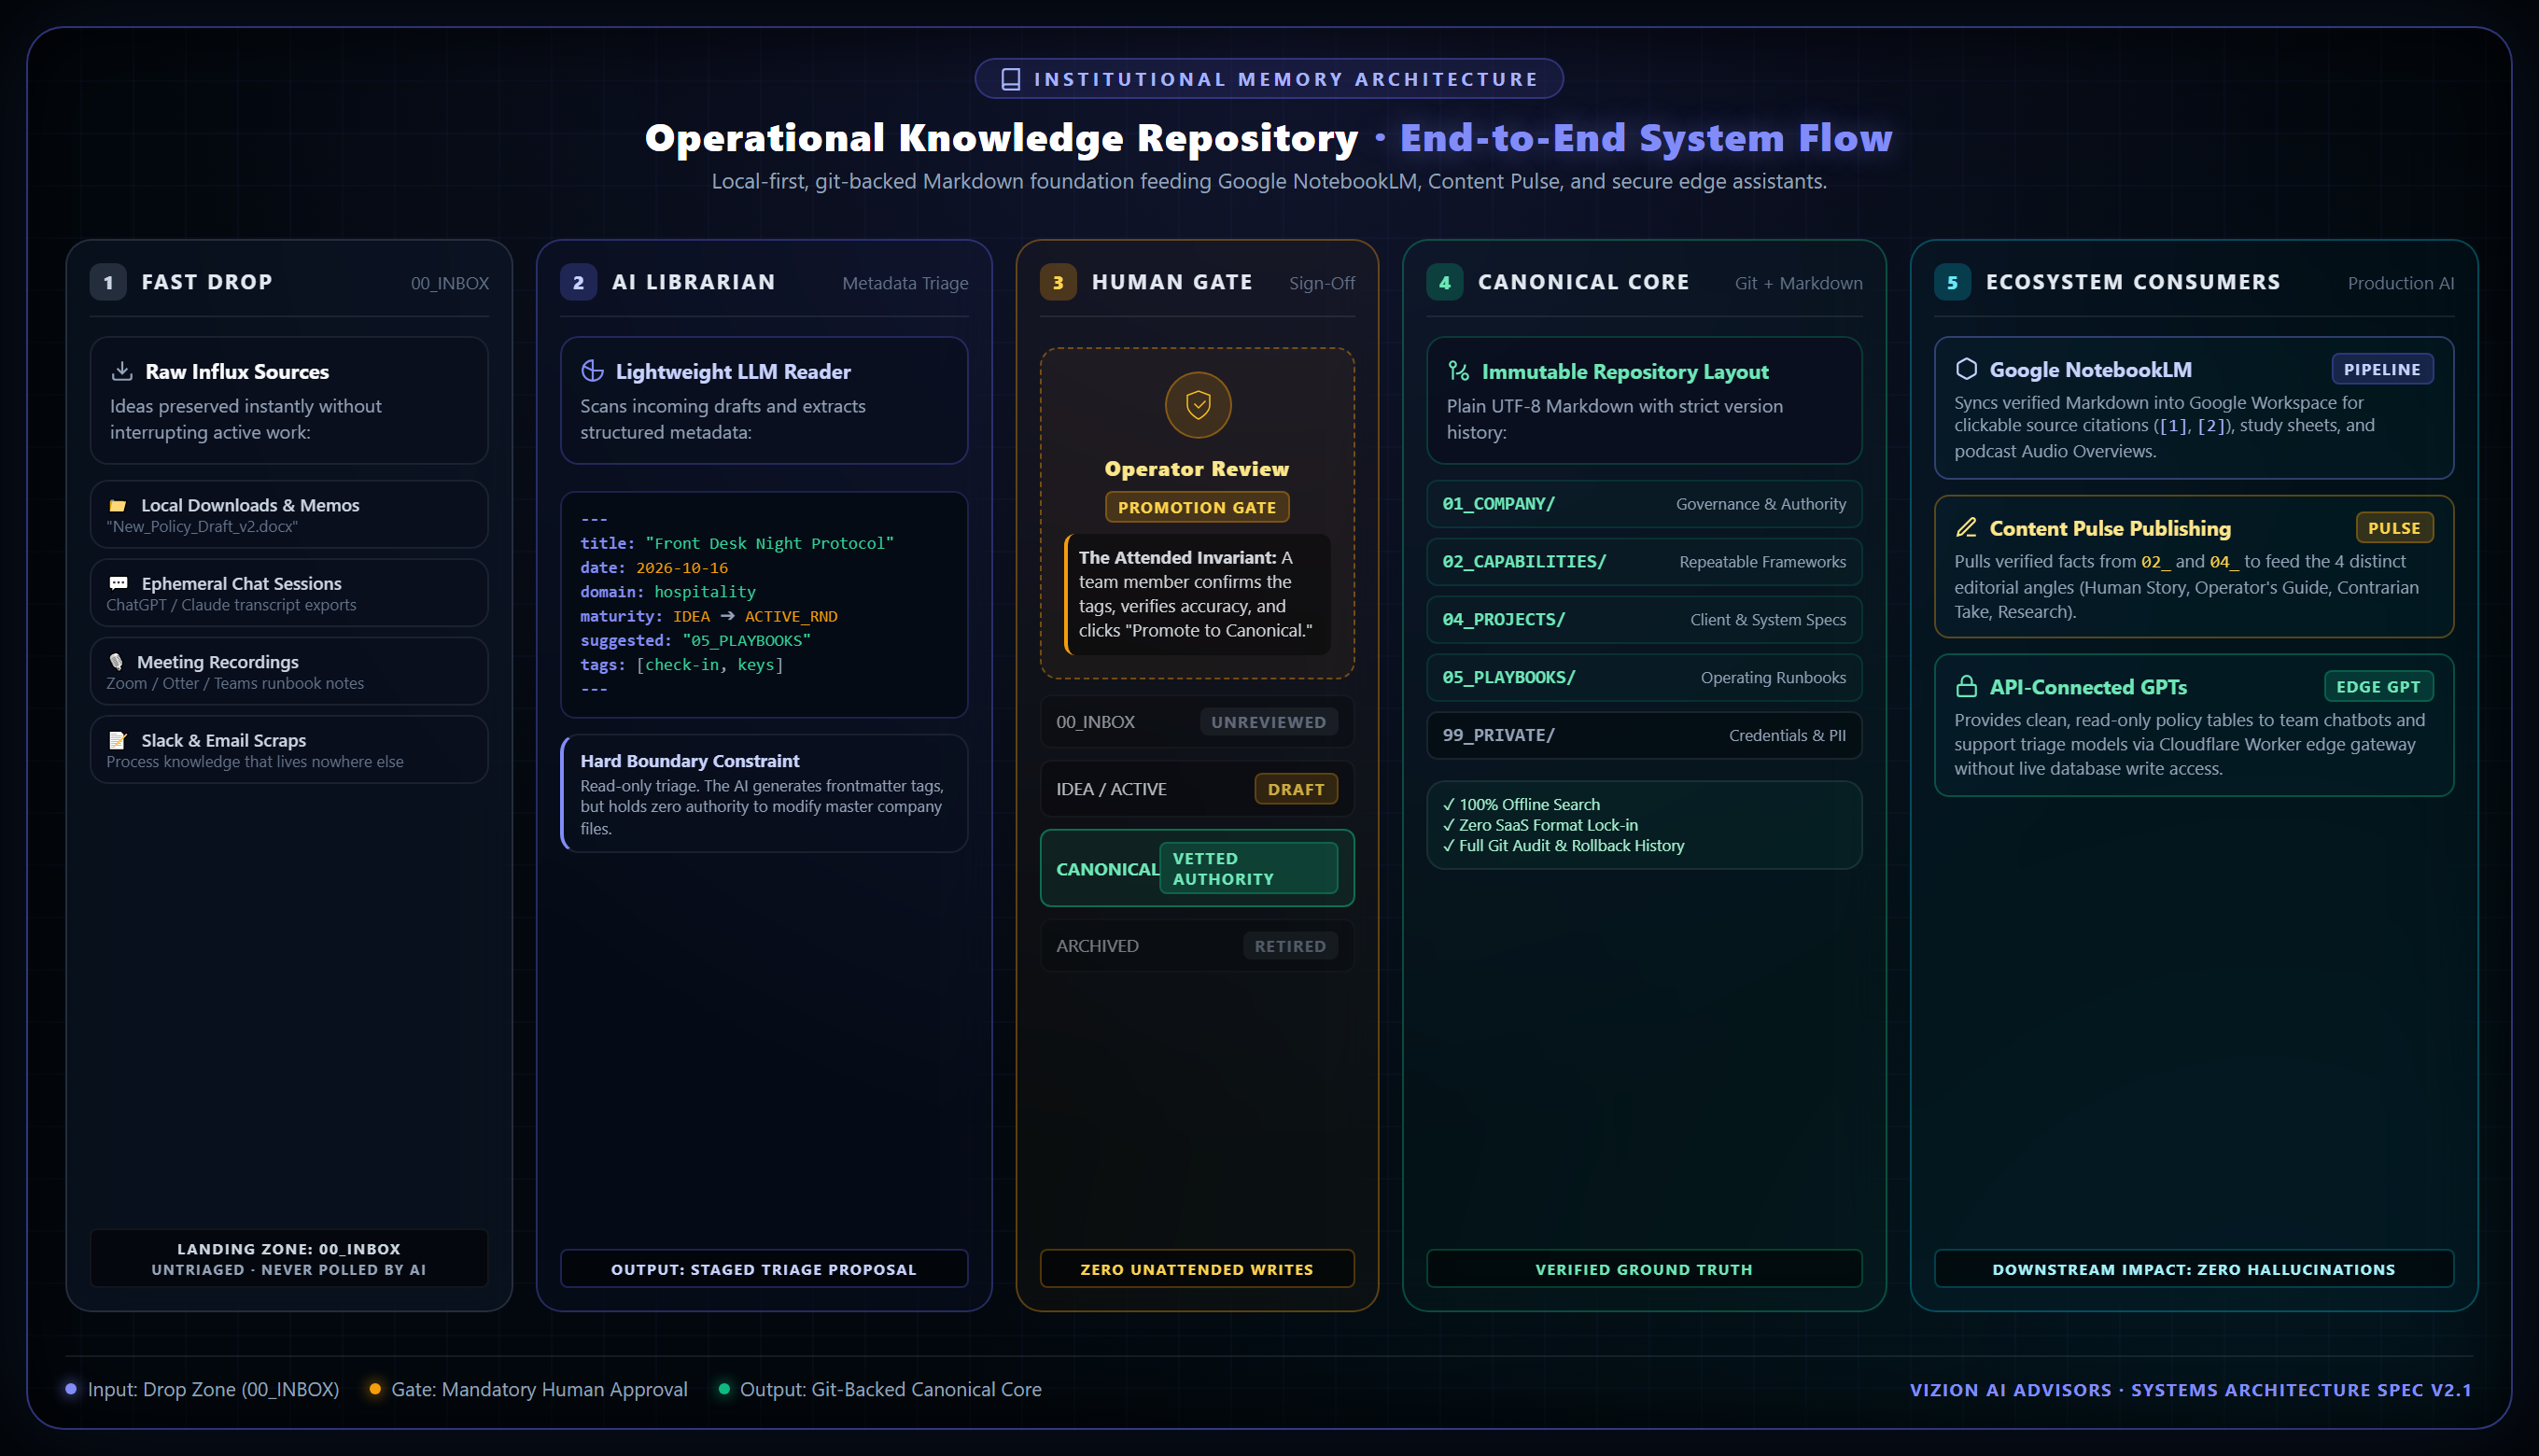
System Architecture & Flow
Starting Baseline Setup & Maintenance
Starting at 10,000 CZK setup · 10,000 CZK / mo
(approx. €420 setup · €420 / mo baseline)
The setup fee covers establishing your folder taxonomy, configuring git-backed repository sync, building automated librarian sorting rules, and migrating your first 50 core operational documents.
Shared folders naturally drift into clutter without active oversight. Monthly maintenance covers auditing weekly document classifications, recalibrating triage prompts as company terminology shifts, resolving dead links, and keeping your AI context index clean for everyday team queries.
Final scope depends on existing document volume, multi-department taxonomy requirements, and migration complexity. We clarify the exact scope during discovery before any commitment.
Need to turn hundreds of hours of recorded video and audio into queryable cards? Explore the Knowledge Pipeline.
Keep what was decided.
When an experienced team member steps away, their working context usually goes with them. We organize key procedures, project decisions, and operational runbooks into a durable record your entire team can search and rely on.
Separate rough drafts from active policy.
If you connect an AI assistant to your shared drive today, it will treat a discarded brainstorm from three years ago with the same weight as last week’s signed contract. We set up simple stages so everyone—and every tool—instantly knows what is an active company rule and what was just an exploratory scratchpad.
Files you actually own for the next ten years.
No proprietary cloud database, no monthly seat licenses, and no export headaches. Your notes live on your machine as plain Markdown files. They open in milliseconds, search instantly offline, and stay readable by any software or language model you choose down the road.
Why This Exists
Every growing team tries to build a company wiki. Someone sets up Notion or Confluence, creates twenty nested folders, and asks everyone to document their work.
Within a few months, nobody updates it. Logging into a web app, navigating hierarchies, and formatting pages feels like extra administrative homework during a busy workday. The wiki becomes an outdated ghost town of half-finished drafts and broken links, and people go back to asking questions in Slack.
When teams try to fix this with AI, they usually point a chatbot straight at their shared Google Drive or Dropbox. But language models cannot tell an outdated draft from a current rule. Without clear boundaries, the assistant blends old ideas with active policy, producing confident, wrong answers.
This repository takes the opposite approach. You write in whatever text editor you already use, save notes into a simple inbox folder, and keep working. An AI assistant handles the routine work of suggesting tags, summaries, and folder locations—but a human operator confirms changes before anything is marked as authoritative company policy.
The Reality
Web-based tools add friction. When people are under deadline, they won't stop to navigate a web portal, pick icons, or adjust formatting. Notes stay on local desktops, and documentation dies.
You take notes in seconds on your own laptop. Files sync quietly in the background, open with zero lag, and never depend on a third-party software vendor staying in business.
The Upstream Foundation
How The Repository Connects Your Work
The repository is not an isolated archive. It is the verified upstream filing cabinet that feeds your other systems:
Google NotebookLM (Knowledge Pipeline)
Syncs verified policies and runbooks into private Google notebooks. Your team can ask questions in plain English and get answers with clickable citations pointing back to the exact passage.
Content Pulse Publishing System
Feeds real project notes and case studies directly into our editorial drafting system, turning everyday engineering work into authentic articles and guides.
API-Connected GPTs (Safe Policy Search)
Gives customer support bots and internal assistants safe, read-only access to company handbooks without giving them permission to alter your database.
Challenging Our Own Claims
What Didn't Work & What We Learned
Building a knowledge system that survives day-to-day work requires understanding why most documentation projects collapse. Here are four real breakdowns from our practice, and the engineering rules we built to fix them.
The Draft Confusion Trap
Why connecting an AI directly to Google Drive produces confident errors
Connecting an AI assistant directly to an existing Google Drive or Notion workspace would let staff search company knowledge accurately.
The language model treated a discarded 2022 brainstorming memo titled "Pricing Ideas" with the exact same authority as a 2026 signed contract schedule, blending outdated thoughts with active policy.
We enforce a strict five-stage maturity status on every document. Internal AI assistants are restricted to searching files marked as verified canonical policy.
The SaaS Wiki Graveyard
Why web-based team wikis get abandoned within six months
Setting up a modern, web-based corporate wiki would encourage the team to document processes consistently.
Updating a proprietary web app felt like doing unpaid administrative homework. When the team got busy, updates stopped, leaving a ghost town of outdated pages.
Local-first plain-text Markdown. Team members take notes directly in the text editor they already have open. Zero login latency, instant offline search, and no formatting overhead.
The Unsupervised Filing Illusion
Why AI cannot be left alone to organize company folders
We could write an automated prompt to let an AI read incoming documents and sort them into folders autonomously.
Unsupervised models hallucinated duplicate categories, misjudged project context, and scattered related files across arbitrary folders.
The Attended Librarian pattern. The model reads incoming notes in an inbox, suggests summary metadata and a folder path, but a human operator confirms the placement before any file is promoted.
The Format Lock-In Trap
Why proprietary databases fail the ten-year test
Storing company knowledge inside proprietary cloud databases was safe because they offer export buttons.
When software vendors change pricing tiers or alter APIs, exporting data leaves you with messy JSON blobs, lost formatting, and broken image links that new AI tools struggle to parse.
Standard UTF-8 Markdown with clean YAML metadata headers. Readable on any computer today, and guaranteed to be readable by every operating system and language model ten years from now.
Built for everyday work. Searchable by modern tools.
Proprietary wikis fail because updating them feels like extra homework. By contrast, this repository uses open plain-text Markdown, local-first files, and git sync. You write where you are already comfortable, and lightweight librarian prompts help index and cross-link files without trapping your data.